Your models, your machines
Local GGUF models run through a built-in llama.cpp, accelerated by Metal, Vulkan or CUDA. Cloud models (OpenAI, Anthropic, Gemini) are there when you choose them.
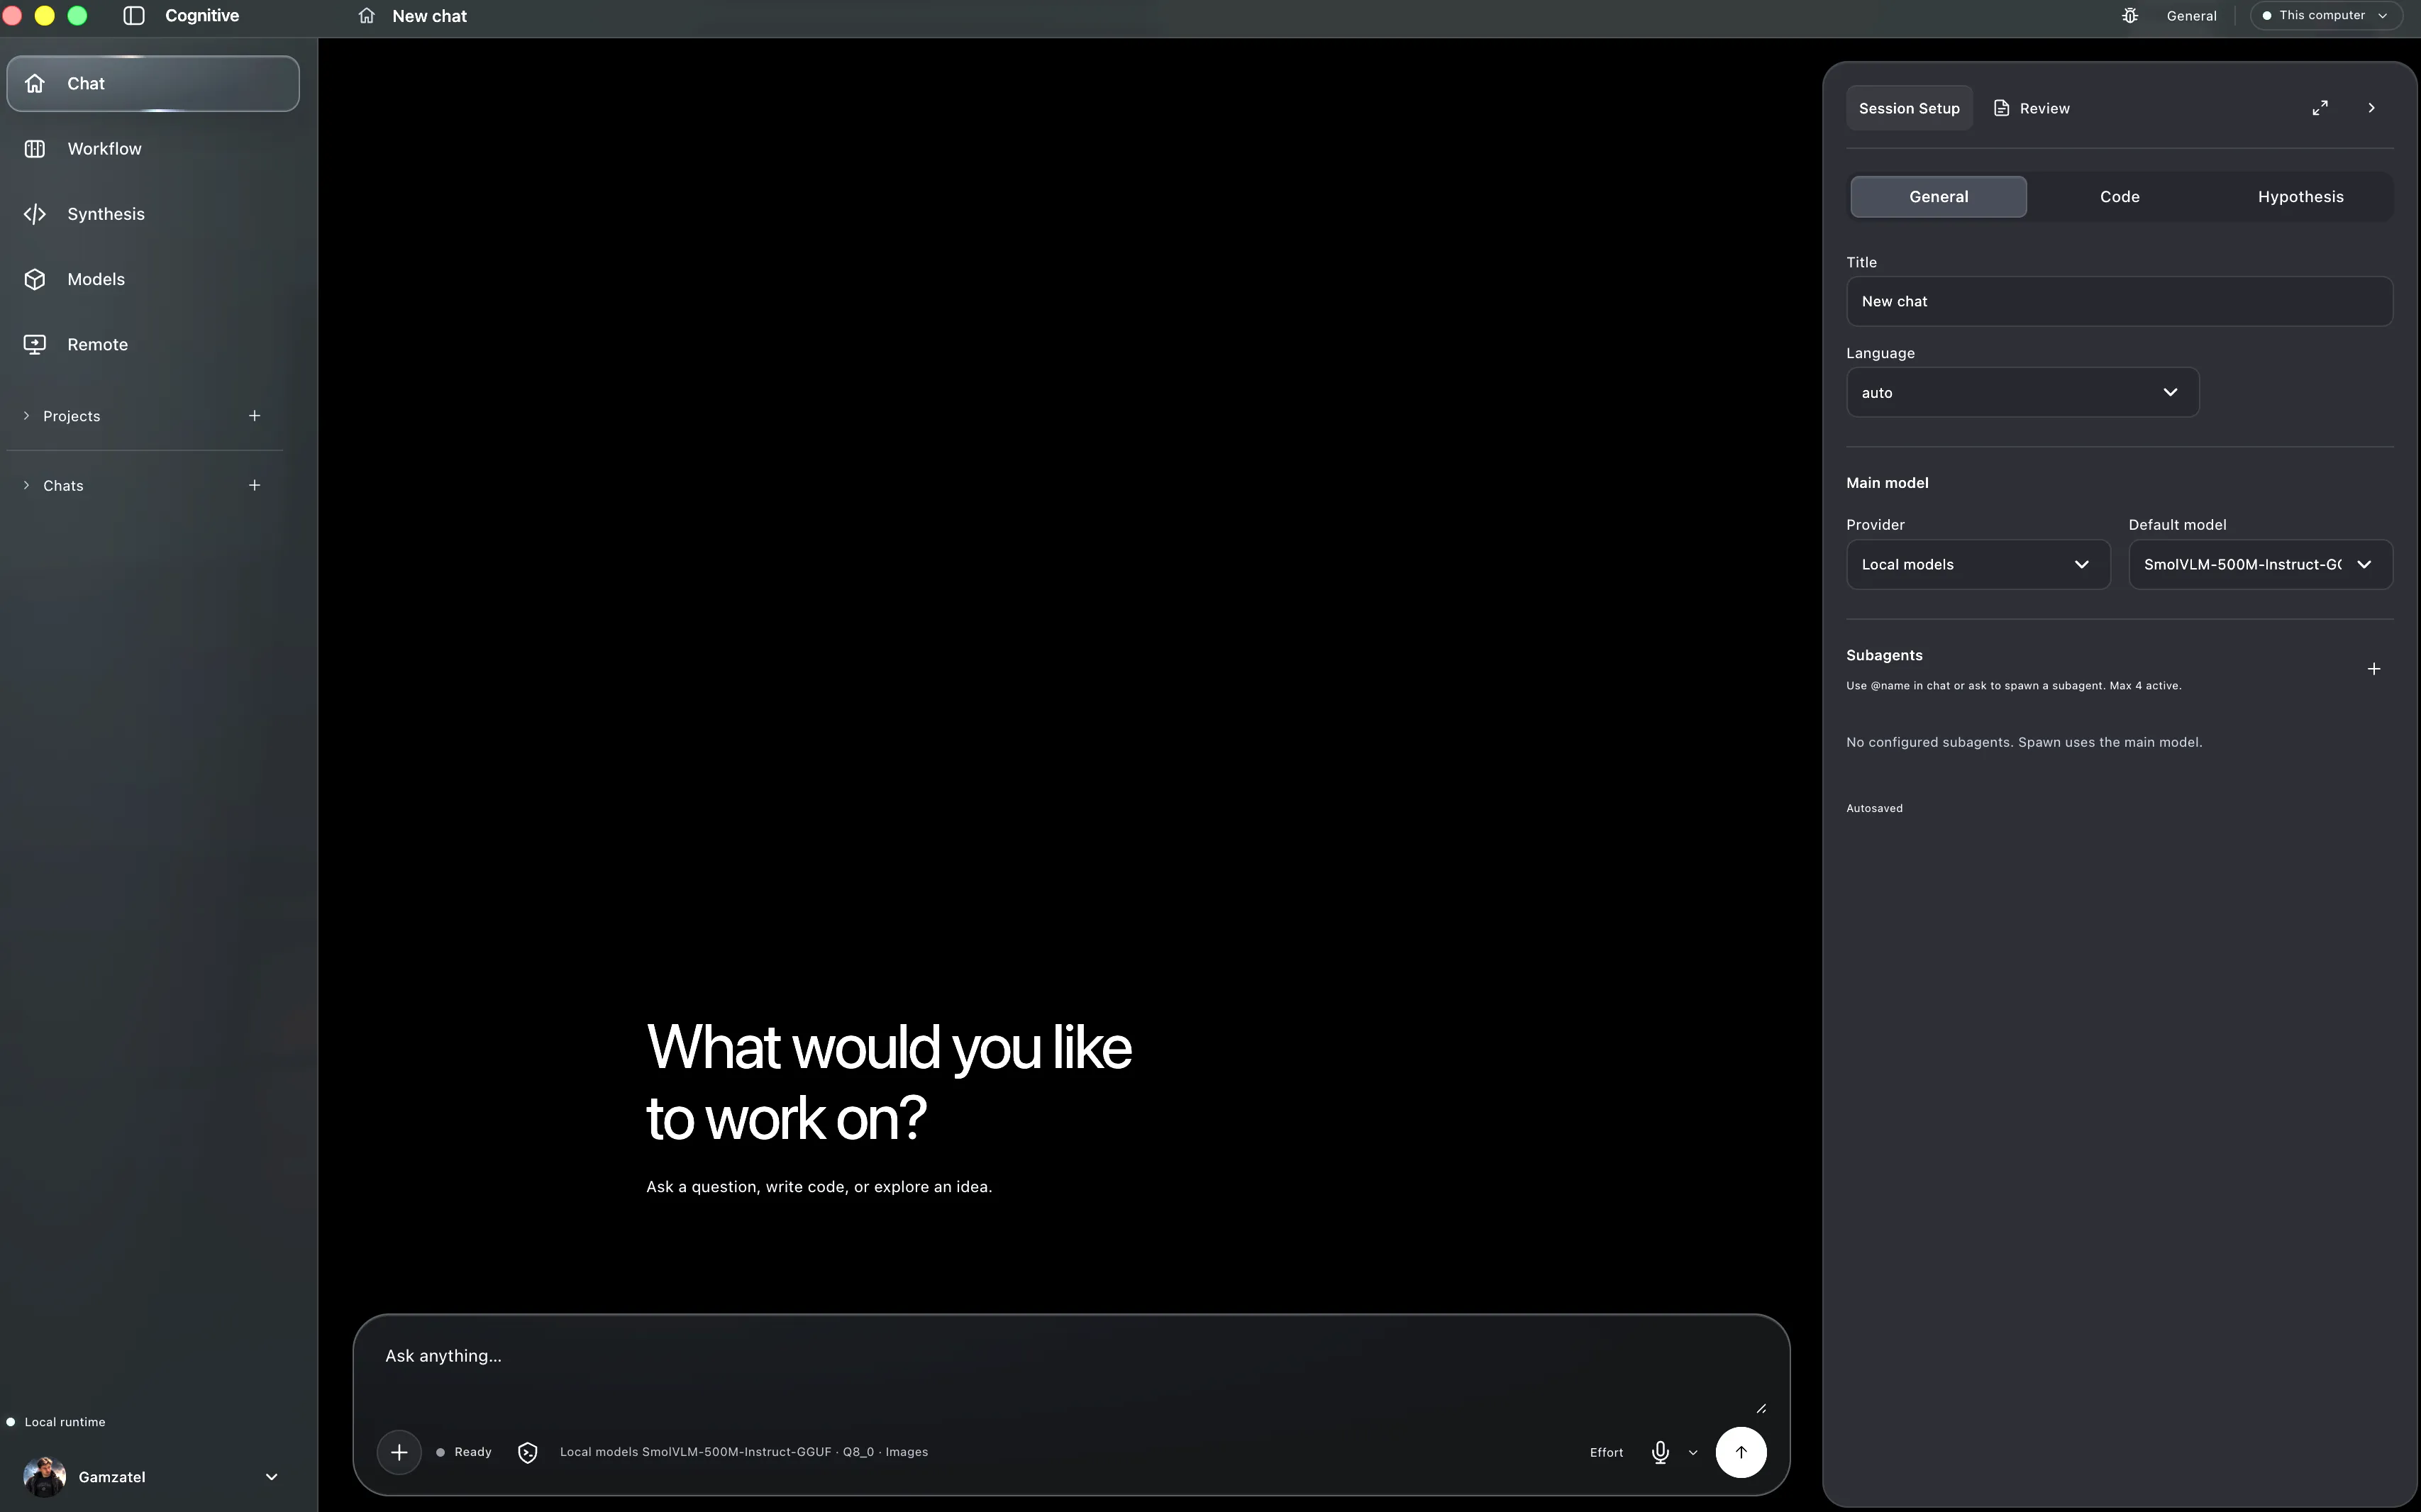
Your models, your machines
Local GGUF models run through a built-in llama.cpp, accelerated by Metal, Vulkan or CUDA. Cloud models (OpenAI, Anthropic, Gemini) are there when you choose them.
A GPU server in one command
Install the server on a Linux machine with NVIDIA GPUs, paste the key it prints into the app, and use it from anywhere. The connection is encrypted end to end.
Agents and workflows
Subagents, debates, a code mode with approvals, a visual workflow builder, tasks and schedules, MCP servers and plugins.
Synthesis
Describe a module’s contract, drive agents with a small flow language, and get code checked against that contract.